Modeling Scalability of Distributed Machine Learning
Alexander Ulanov, Andrey Simanovsky, Manish Marwah
Abstract
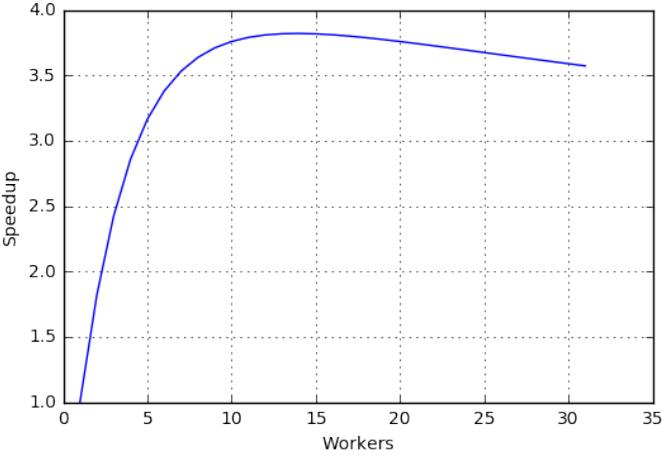
—Present day machine learning is computationally intensive and processes large amounts of data. It is implemented in a distributed fashion in order to address these scalability issues. The work is parallelized across a number of computing nodes. It is usually hard to estimate in advance how many nodes to use for a particular workload. We propose a simple framework for estimating the scalability of distributed machine learning algorithms. We measure the scalability by means of the speedup an algorithm achieves with more nodes. We propose time complexity models for gradient descent and graphical model inference. We validate our models with experiments on deep learning training and belief propagation. This framework was used to study the scalability of machine learning algorithms in Apache Spark.
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…