Gradient Descent based Optimization Algorithms for Deep Learning Models Training
Jiawei Zhang
Abstract
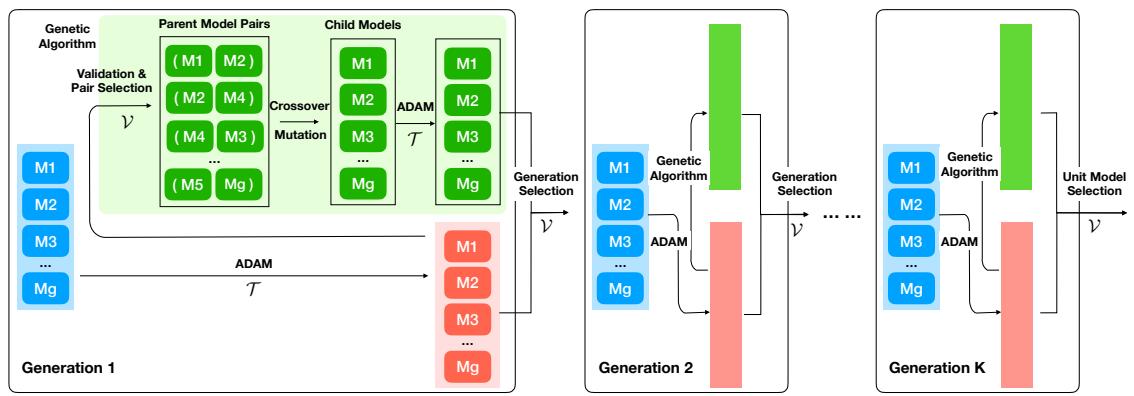
In this paper, we aim at providing an introduction to the gradient descent based optimization algorithms for learning deep neural network models. Deep learning models involving multiple nonlinear projection layers are very challenging to train. Nowadays, most of the deep learning model training still relies on the back propagation algorithm actually. In back propagation, the model variables will be updated iteratively until convergence with gradient descent based optimization algorithms. Besides the conventional vanilla gradient descent algorithm, many gradient descent variants have also been proposed in recent years to improve the learning performance, including Momentum, Adagrad, Adam, Gadam, etc., which will all be introduced in this paper respectively.
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…