Deformable Graph Transformer
Jinyoung Park, Seongjun Yun, Hyeonjin Park, Jaewoo Kang, Jisu Jeong, Kyung-Min Kim, Jung-Woo Ha, Hyunwoo J. Kim
Abstract
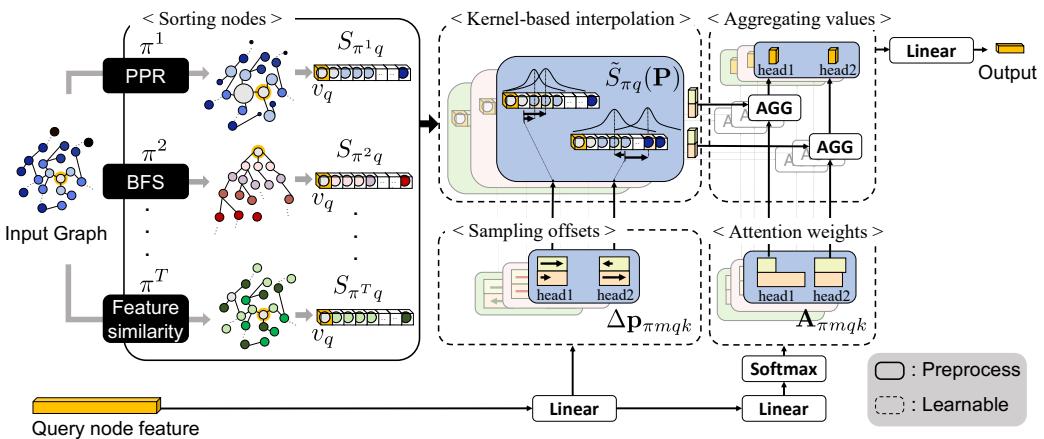
'Kyung-Min Kim' 'Jung-Woo Ha' 'Hyunwoo J. Kim'] Transformer-based models have recently shown success in representation learning on graph-structured data beyond natural language processing and computer vision. However, the success is limited to small-scale graphs due to the drawbacks of full dot-product attention on graphs such as the quadratic complexity with respect to the number of nodes and message aggregation from enormous irrelevant nodes. To address these issues, we propose Deformable Graph Transformer (DGT) that performs sparse attention via dynamically sampled relevant nodes for efficiently handling large-scale graphs with a linear complexity in the number of nodes. Specifically, our framework first constructs multiple node sequences with various criteria to consider both structural and semantic proximity. Then, combining with our learnable Katz Positional Encodings, the sparse attention is applied to the node sequences for learning node representations with a significantly reduced computational cost. Extensive experiments demonstrate that our DGT achieves state-of-the-art performance on 7 graph benchmark datasets with 2.5 ∼ 449 times less computational cost compared to transformer-based graph models with full attention.
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…