Multi-Modal interpretable automatic video captioning
Antoine Hanna-Asaad, Decky Aspandi, Titus Zaharia
Abstract
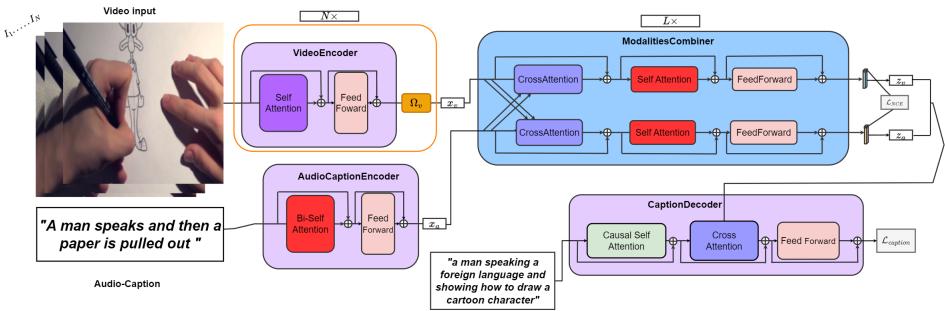
Video captioning aims to describe video contents using natural language format that involves understanding and interpreting scenes, actions and events that occurs simultaneously on the view. Current approaches have mainly concentrated on visual cues, often neglecting the rich information available from other important modality of audio information, including their inter-dependencies. In this work, we introduce a novel video captioning method trained with multi-modal contrastive loss that emphasizes both multi-modal integration and interpretability. Our approach is designed to capture the dependency between these modalities, resulting in more accurate, thus pertinent captions. Furthermore, we highlight the importance of interpretability, employing multiple attention mechanisms that provide explanation into the model's decision-making process. Our experimental results demonstrate that our proposed method performs favorably against the state-of the-art models on commonly used benchmark datasets of MSR-VTT and VATEX.
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…