Conformal Feedback Alignment: Quantifying Answer-Level Reliability for Robust LLM Alignment
Tiejin Chen, Xiaoou Liu, Vishnu Nandam, Kuan-Ru Liou, Hua Wei
Abstract
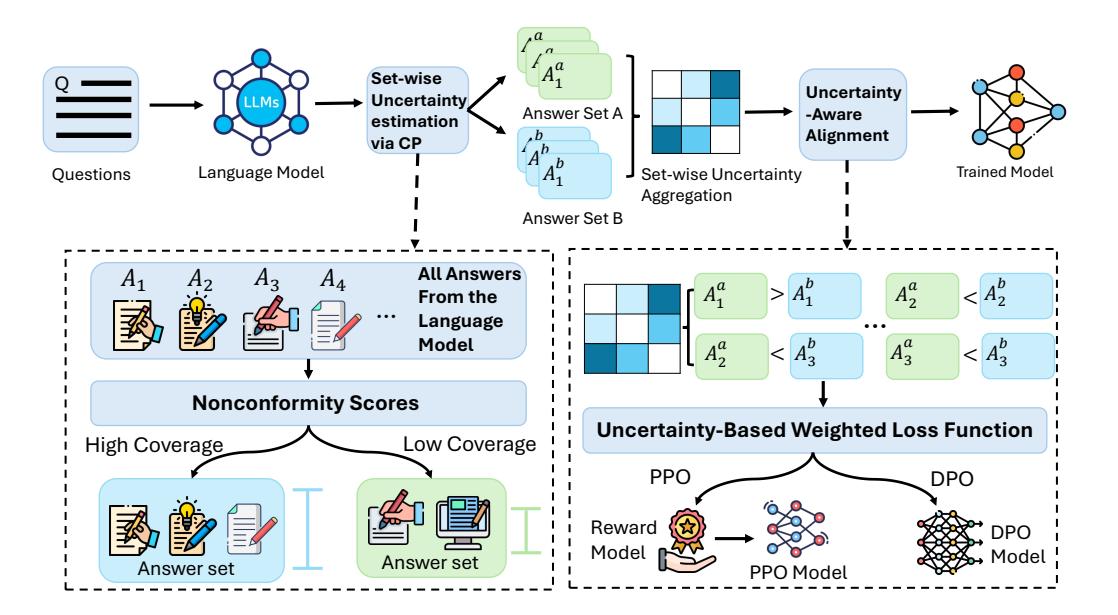
Preference-based alignment like Reinforcement Learning from Human Feedback (RLHF) learns from pairwise preferences, yet the labels are often noisy and inconsistent. Existing uncertainty-aware approaches weight preferences, but ignore a more fundamental factor: the reliability of the answers being compared. To address the problem, we propose Conformal Feedback Alignment (CFA), a framework that grounds preference weighting in the statistical guarantees of Conformal Prediction (CP). CFA quantifies answer-level reliability by constructing conformal prediction sets with controllable coverage and aggregates these reliabilities into principled weights for both DPOand PPO-style training. Experiments across different datasets show that CFA improves alignment robustness and data efficiency, highlighting that modeling answer-side uncertainty complements preference-level weighting and yields more robust, data-efficient alignment. Codes are provided here.
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…