Cross-Attention and Encoder-Decoder Transformers: A Logical Characterization
Veeti Ahvonen, Damian Heiman, Antti Kuusisto, Miguel Moreno, Matias Selin
Abstract
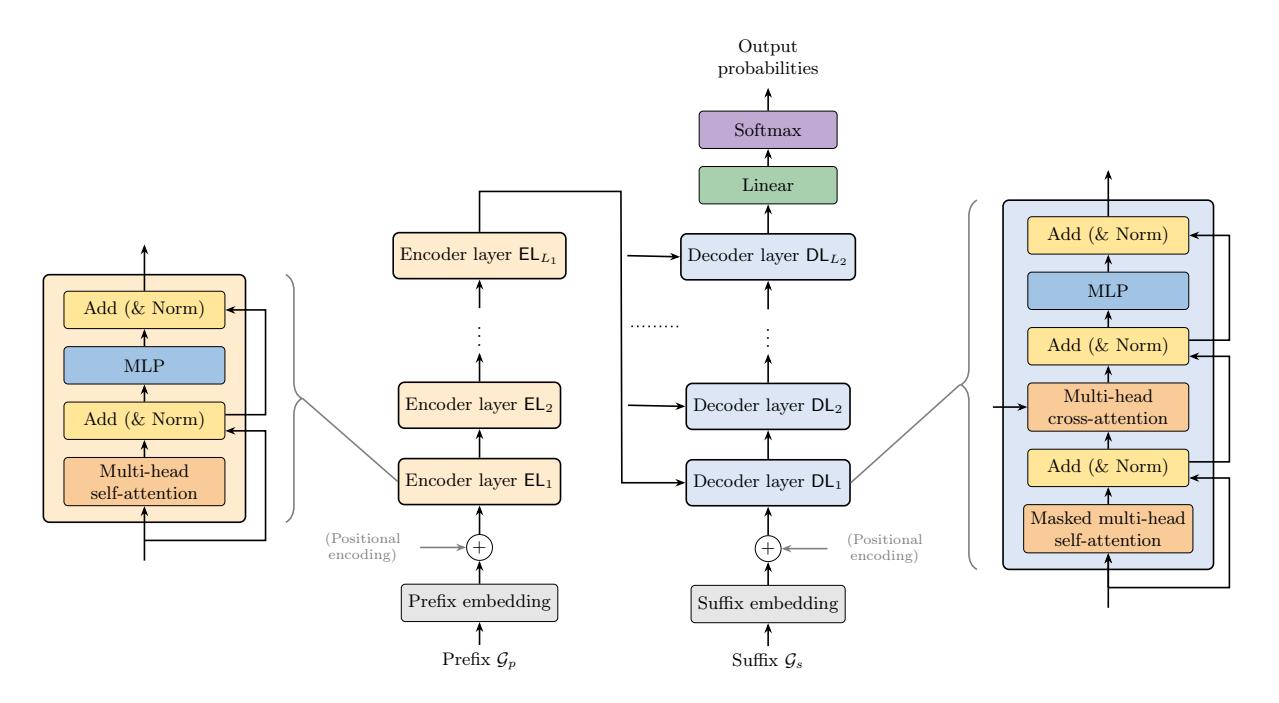
We give a novel logical characterization of encoder-decoder transformers, the foundational architecture for LLMs that also sees use in various settings that benefit from cross-attention. We study such transformers over text in the practical setting of floating-point numbers and soft-attention, characterizing them with a new temporal logic. This logic extends propositional logic with a counting global modality over the encoder input and a past modality over the decoder input. We also give an additional characterization of such transformers via a type of distributed automata, and show that our results are not limited to the specific choices in the architecture and can account for changes in, e.g., masking. Finally, we discuss encoder-decoder transformers in the autoregressive setting.
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…