Efficient toolkit implementing best practices for principal component analysis of population genetic data
Florian Privé, Keurcien Luu, Michael G B Blum, John J McGrath, Bjarni J Vilhjálmsson, Russell Schwartz
Abstract
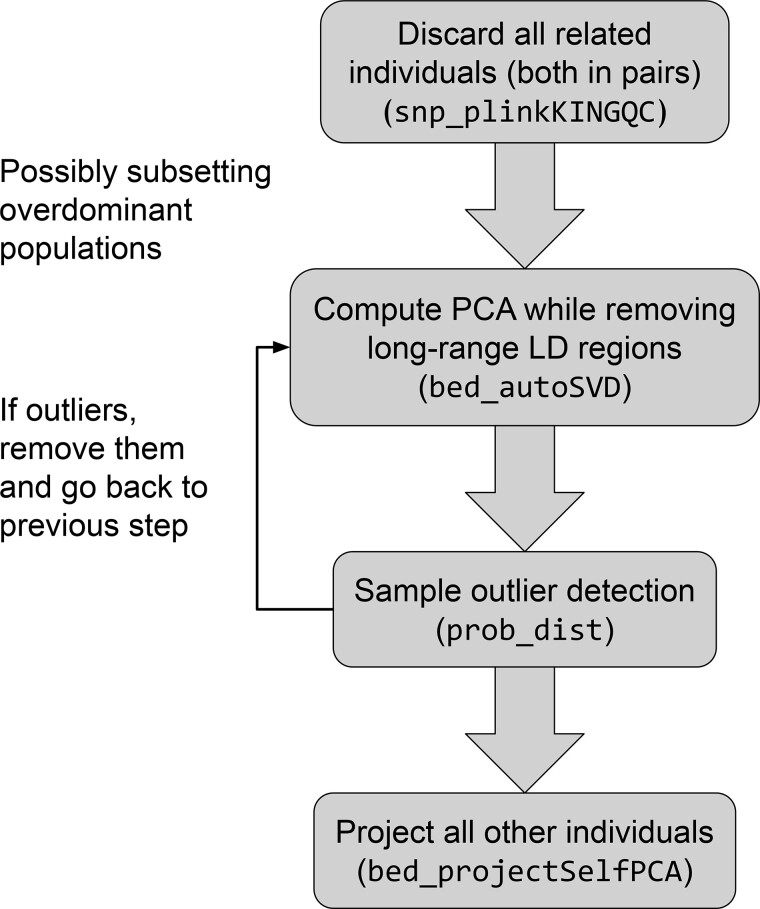
In this work, we have compiled different pitfalls that can arise with PCA of genetic data. Then, we have investigated possible solutions to these pitfalls and selected the ones that we found most advantageous, both with respect to properties such as accuracy and robustness, but also computational efficiency and ease of use. We then implemented these solutions in R packages bigsnpr and bigutilsr. The new functions we provide in R package bigsnpr can be directly applied to genotypes stored as PLINK bed/bim/fam files with some missing values. This contrasts with previous releases of package bigsn
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…