A Hierarchical Spatial–Temporal Cross-Attention Scheme for Video Summarization Using Contrastive Learning
Xiaoyu Teng, Xiaolin Gui, Pan Xu, Jianglei Tong, Jian An, Yang Liu, Huilan Jiang, Kang Ryoung Park, Sangyoun Lee, Euntai Kim
Abstract
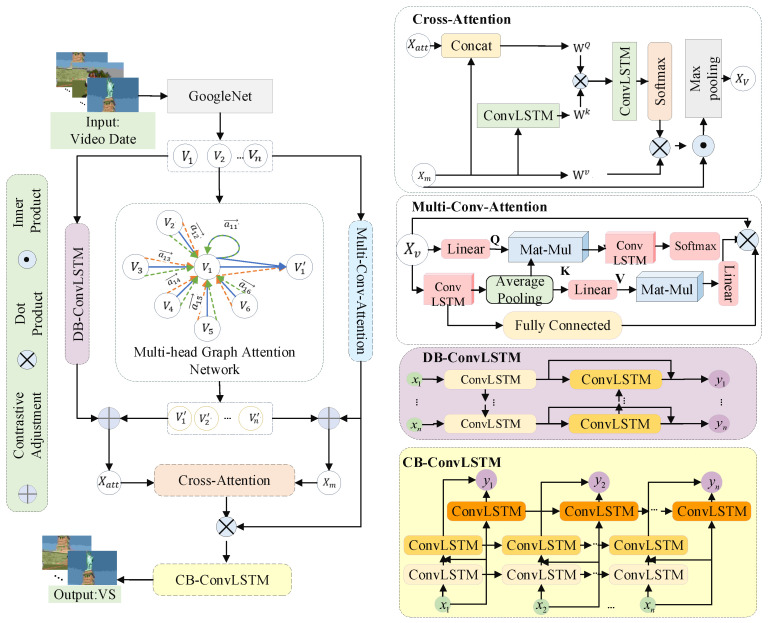
'Huilan Jiang' 'Kang Ryoung Park' 'Sangyoun Lee' 'Euntai Kim'] Video summarization (VS) is a widely used technique for facilitating the effective reading, fast comprehension, and effective retrieval of video content. Certain properties of the new video data, such as a lack of prominent emphasis and a fuzzy theme development border, disturb the original thinking mode based on video feature information. Moreover, it introduces new challenges to the extraction of video depth and breadth features. In addition, the diversity of user requirements creates additional complications for more accurate keyframe screening issues. To overcome these challenges, this paper proposes a hierarchical spatial-temporal cross-attention scheme for video summarization based on comparative learning. Graph attention networks (GAT) and the multi-head convolutional attention cell are used to extract local and depth features, while the GAT-adjusted bidirection ConvLSTM (DB-ConvLSTM) is used to extract global and breadth features. Furthermore, a spatial-temporal cross-attention-based ConvLSTM is developed for merging hierarchical characteristics and achieving more accurate screening in similar keyframes clusters. Verification experiments and comparative analysis demonstrate that our method outperforms state-of-the-art methods.
§ The Valyu brief
Reading the full paper and taking notes. This takes a few seconds…
§ Ask this paper
Ask a question about this paper
Valyu reads the full text and answers from what the paper actually says.
Searching the other archives…